DataLoader
The Dataset gave us a stream of individual (input, target) chunks. But a model does not train on one chunk at a time. It trains on a batch: several chunks stacked together and processed in one go. Turning chunks into batches is the job of the DataLoader.
The DataLoader wraps a Dataset and does three things: it groups chunks into batches of a fixed batchSize, optionally shuffles their order each pass, and can convert each batch into a tensor ready for the model.
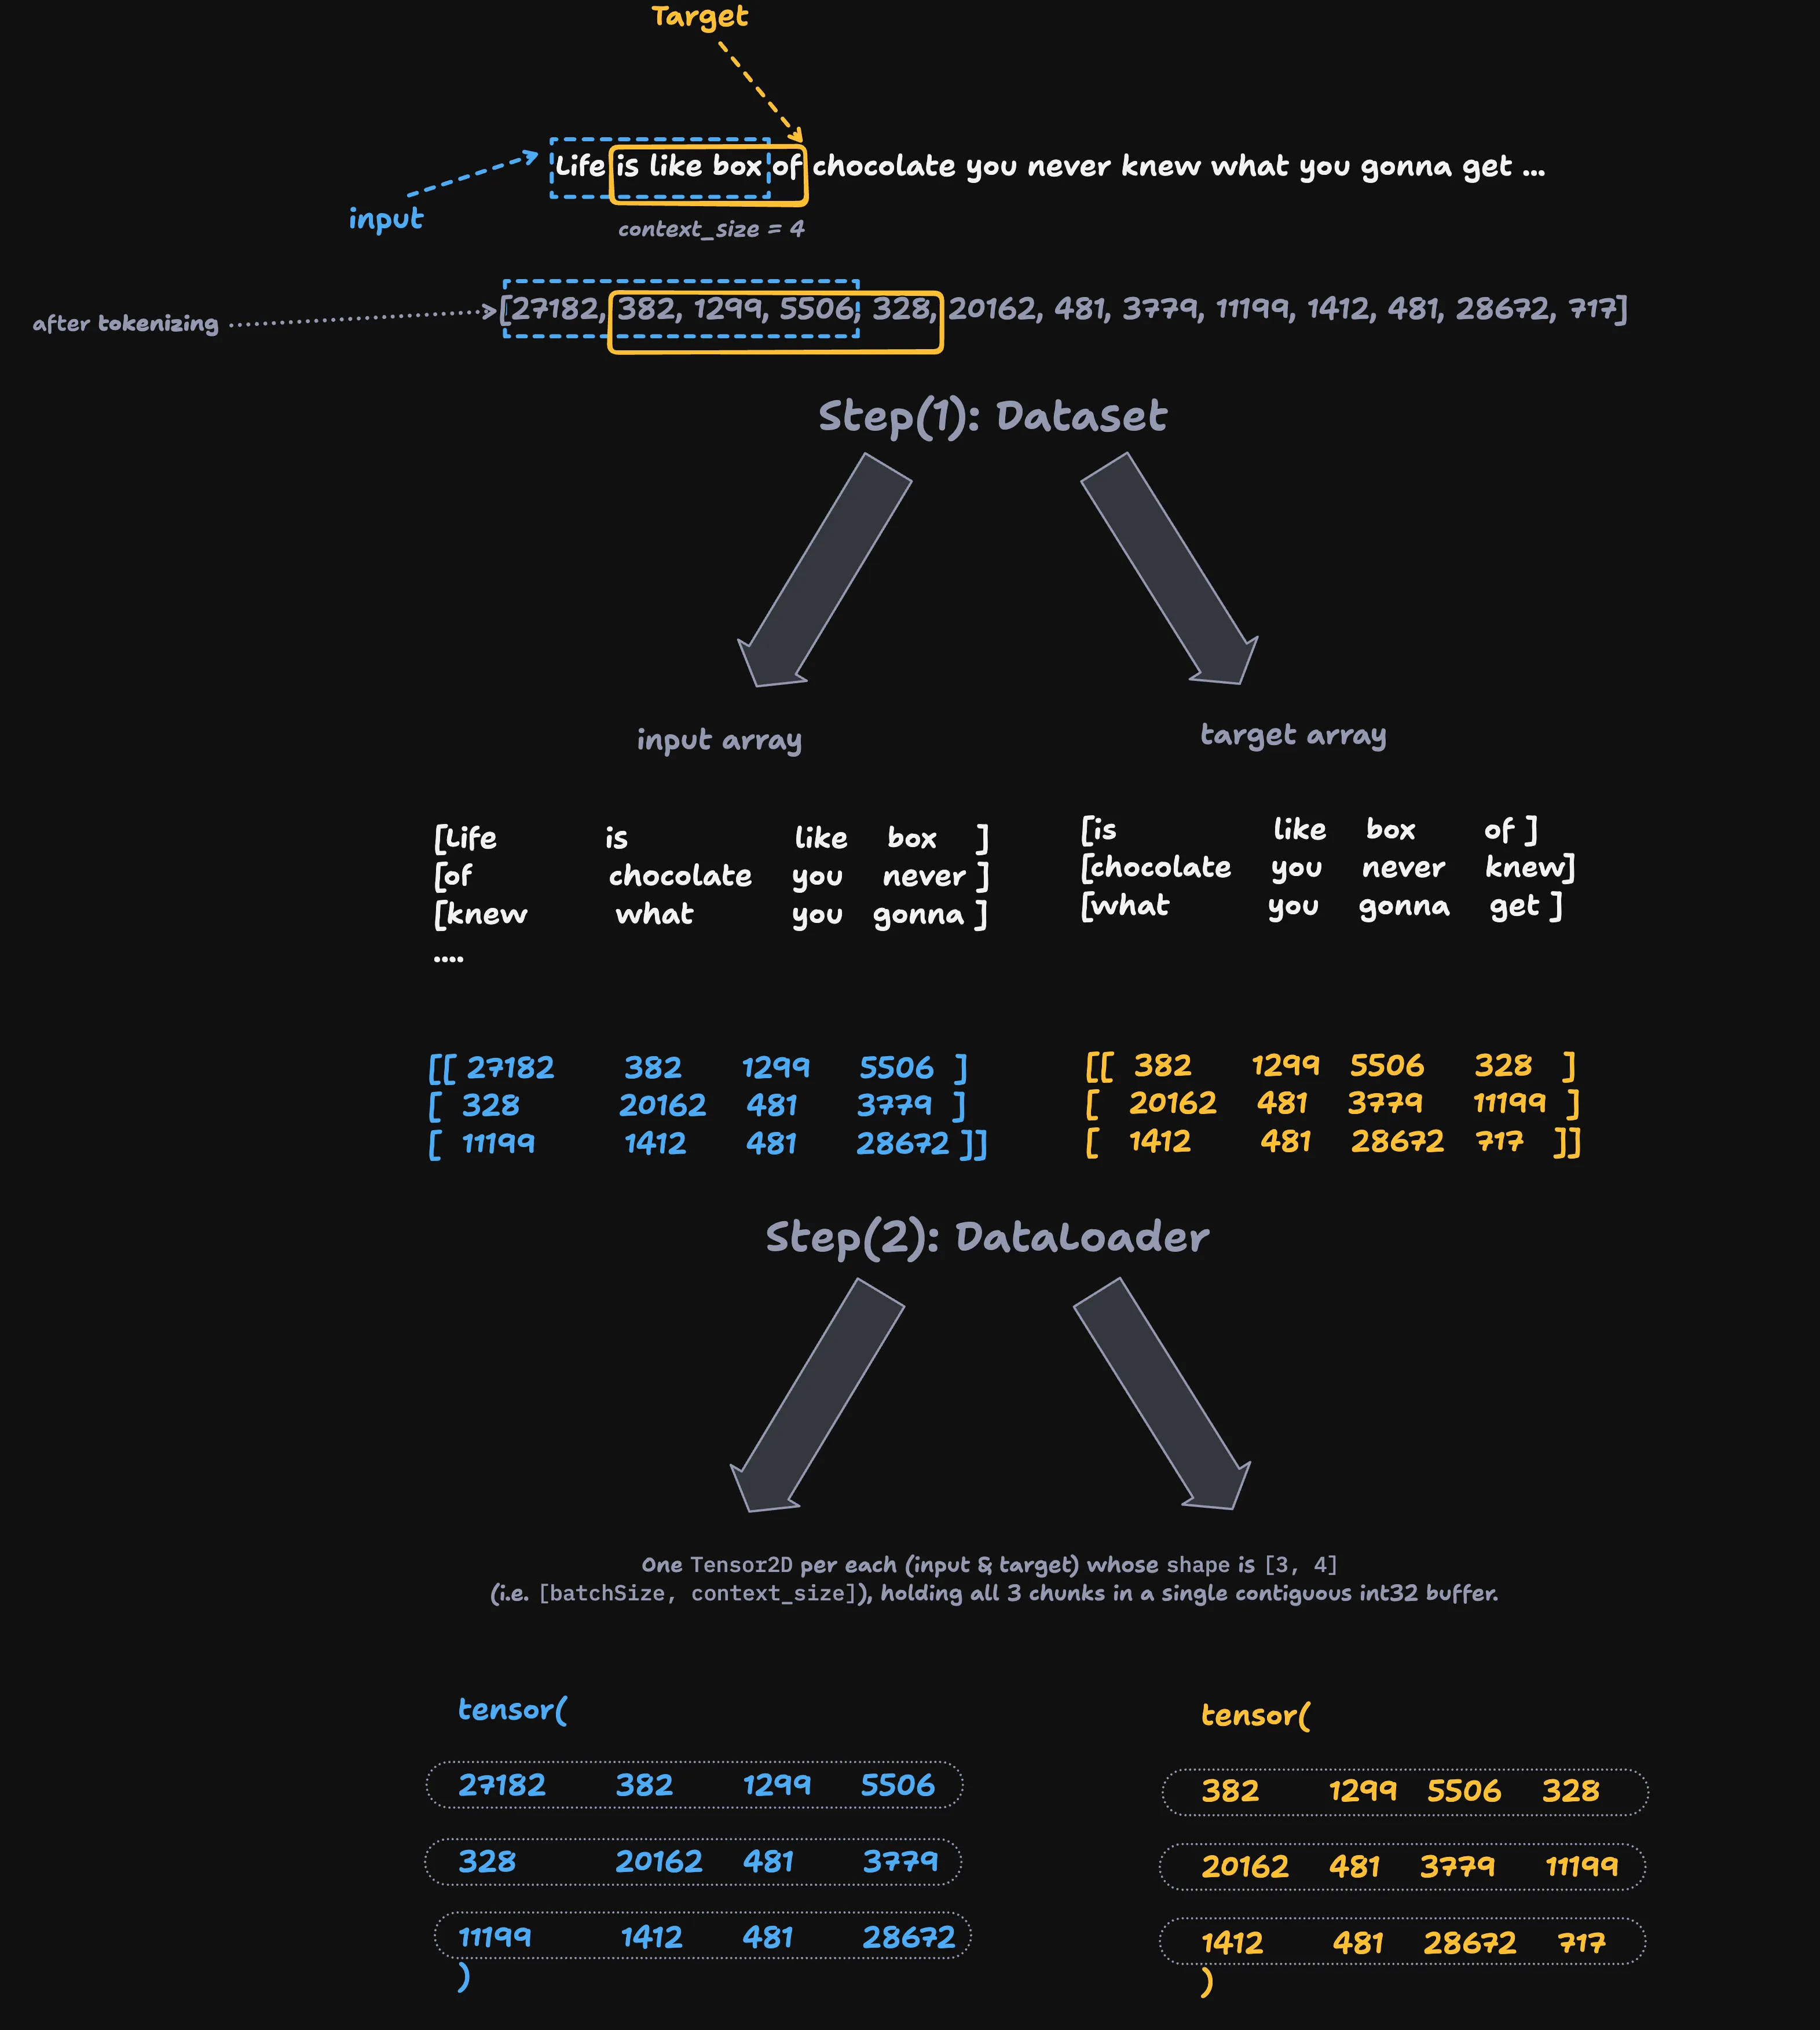
From chunks to batches
Section titled “From chunks to batches”Notice the boundary between the two classes. The Dataset produces the individual chunk rows. The DataLoader is what stacks batchSize of those rows into a rectangular grid of shape [batchSize, context_size]. So for a batchSize of 3 and a context_size of 4, one batch of inputs is a 3 by 4 grid: three chunks, four tokens each.
for (let start = 0; start < indices.length; start += batchSize) {  // Take the next `batchSize` chunk indices (shuffled or in order).  const slice = indices.slice(start, start + batchSize);  const samples = slice.map((i) => dataset.at(i));
  // Stack the chunks into two grids of shape [batchSize, context_size].  const inputs = samples.map((s) => s.input);  const targets = samples.map((s) => s.target);
  yield { inputs, targets };}
Shuffling matters because it stops the model from learning the accidental order of the text. Before each pass we shuffle the list of chunk indices, not the tokens inside a chunk, so every batch sees a fresh mix while each chunk stays intact.
Tensor batches
Section titled “Tensor batches”By default the DataLoader hands back plain JavaScript arrays. Pass asTensors: true and each batch instead becomes a single Tensor2D of shape [batchSize, context_size], holding all the chunks in one contiguous int32 buffer.
const batch = { inputs: tf.tensor2d(inputs, undefined, "int32"), // one [batchSize, context_size] tensor targets: tf.tensor2d(targets, undefined, "int32"),};This is the payoff from the previous lesson: because the whole batch lives in one tensor, the model runs its math on all the chunks at once, on CPU or GPU, instead of looping chunk by chunk. It is a single tensor per batch, not one tensor per chunk.
PyTorch → JS mapping
Section titled “PyTorch → JS mapping”| Reference (Python) | Here (TypeScript) |
|---|---|
torch.utils.data.DataLoader |
DataLoader |
batch_size / shuffle |
batchSize / shuffle |
drop_last |
dropLast |
| tensor batch (default) | asTensors: true |
- The Dataset produces individual chunks; the DataLoader groups
batchSizeof them into a batch of shape[batchSize, context_size]. - Shuffling reorders chunk indices each pass so the model never learns the text’s accidental order.
- With
asTensors: true, each batch becomes a single int32Tensor2D, ready to feed straight into the model.